Why ambiguous instructions change model behavior
You’ve seen it: you ask for a “quick summary,” and you get either three bullet points or a page of context, or a tone that feels oddly formal. That swing usually isn’t random. When instructions leave room for interpretation, the model has to fill gaps about audience, depth, format, and what “good” looks like. Different reasonable guesses produce very different outputs.
Ambiguity also shifts risk. If “research this” doesn’t say whether you want cautious sourcing or fast synthesis, the model may generalize, hedge, or overconfidently state details. Adding clarity has a cost—more time upfront and sometimes less creative breadth—but it trades surprise for control, which is often the better deal in product, analysis, and automation work.
Spotting ambiguity: where prompts quietly go wrong
Two AI responses may both seem acceptable yet still miss the intended result. The prompt may have seemed clear because you already understood the audience, the background, and what should be left out. Unless those details appear in the instructions, the model has to infer them. Words such as “brief,” “actionable,” “high-level,” “best,” and “safe” leave room for different interpretations, so the model fills in the missing decisions itself.
Ambiguity also arises when several requirements pull in different directions. Asking for a one-page memo that includes every detail and remains punchy forces the model to decide what deserves space. Undefined terms create similar problems: “the plan,” “the stakeholders,” “the policy,” and “the latest” may refer to different things depending on the context. The expected format needs equal care. Specify whether the response should use bullet points or continuous prose, explain the issue or recommend an action, or provide finished copy rather than an outline for further editing.
When the model must guess: typical failure patterns
You usually feel the “guessing” in a handful of repeatable ways. Scope creep is the big one: “overview” turns into background history, definitions, and a mini literature review because the model can’t tell where you want to stop. The opposite happens too—over-compression—where “summarize” becomes a list of headlines with none of the decision-relevant context you expected. Format drift is another pattern: you ask for “a draft,” and it returns an outline, or you ask for “steps,” and it writes an essay.
Ambiguity also triggers tone and certainty failures. Vague prompts invite generic, corporate-sounding language because it’s broadly “safe,” while missing sourcing expectations can lead to confident-sounding claims that aren’t verifiable. When constraints conflict, the model tends to satisfy the most concrete instruction (word count, bullets, template) and quietly sacrifice the fuzzier goal (clarity, completeness, nuance). You spend time editing symptoms instead of fixing the missing decision that caused them.
Different kinds of ambiguity need different fixes
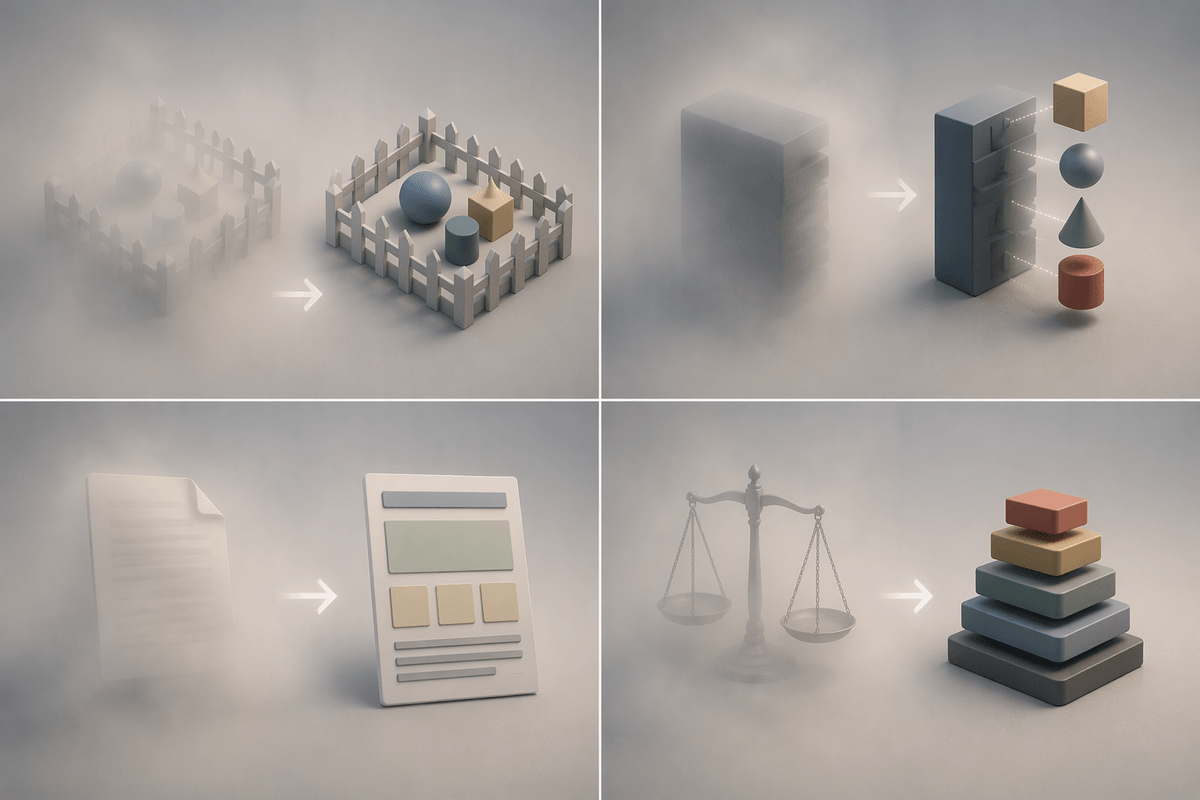
Asking the model to “be more specific” may not solve the problem because ambiguity can come from several different sources. Scope ambiguity concerns what belongs in the answer, what should be left out, and which time period matters. Set clear boundaries, such as “focus on Q3 launch risks, not market history,” and define a stopping rule: include only issues that could affect the decision.
Definition ambiguity arises when everyday terms have different meanings to different people. Words such as “stakeholder,” “latest,” “actionable,” “safe,” and “best” need clearer definitions when they influence the result. Name the intended groups, for example, “stakeholders means Finance, Legal, and Sales Operations,” or explain the standard to apply, such as “actionable means one team can complete the task within two weeks.” Output ambiguity requires similar attention. Specify whether the response should be a memo or bullet list, internal guidance or customer-facing copy, a finished draft or an editable outline. A template and a brief example can make those expectations easier to follow.
Conflicting requirements need an explicit order of priority. A one-page limit may not be compatible with including every detail, so state which requirement takes precedence and what should be preserved if space runs short. Defining these priorities may seem overly meticulous, but it leaves less room for the model to make its own decisions about what matters most.
Make intent testable: constraints, examples, and rubrics
You can’t reliably “get what you mean” until “good” becomes checkable. A constraint is a test: 180–220 words, 5 bullets, no acronyms, cite sources or don’t, include risks before benefits, end with a recommendation. These aren’t pedantic; they let you verify compliance without debating tone. Add boundaries that reflect real work: “assume the reader is a VP with 2 minutes,” “exclude implementation details,” “use only the information in the pasted notes.” If you need creativity, constrain the evaluation instead (“surprising but plausible; no factual claims”).
Examples make intent concrete faster than extra adjectives. One “good” mini-sample (even 2–3 lines) shows format, density, and voice. A “bad” counterexample is often more powerful: “don’t write generic fluff like ‘leverage synergies.’” When quality matters, use a lightweight rubric: accuracy (no invented specifics), relevance (every point ties to the decision), completeness (covers top 3 risks), and usability (clear next step). Rubrics add upfront cost, but they sharply reduce revision cycles and hidden assumption fights.
A simple iteration loop to de-ambiguate prompts fast
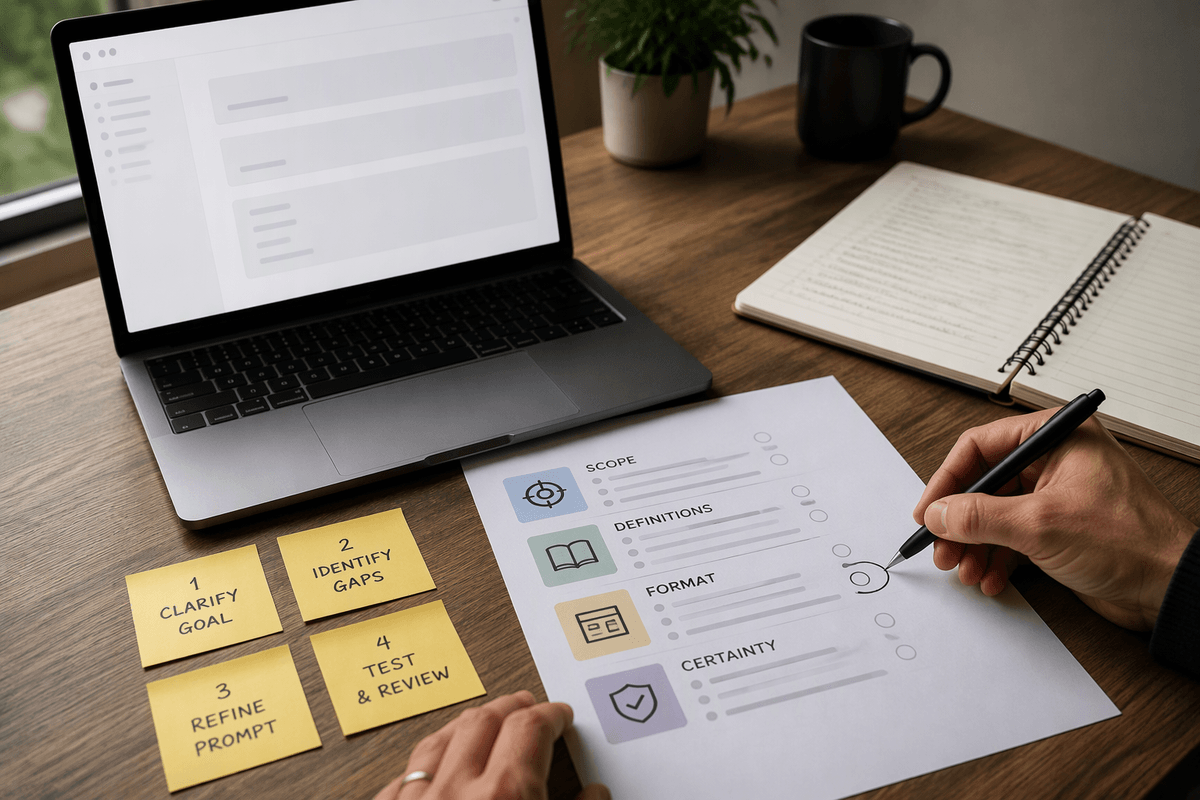
A fast way to tighten a prompt is to treat the first answer as a diagnostic, not a deliverable. Start with a minimal spec: audience, output shape, length, and one or two “must include” items. Run it once. Then mark the gaps using the same lens each time: scope (what it added or missed), definitions (what it interpreted loosely), format (what it ignored), and certainty (where it sounded sure without support).
On the second pass, don’t add more adjectives. Add one concrete test per failure: an inclusion/exclusion rule, a priority order, or a micro-example. If you got fluff, require evidence of work (“each bullet must reference a fact from the notes”). If you got hallucinated specifics, add a hard boundary (“if unknown, say ‘not provided’ and ask 2 questions”). Repeat until changes stop improving outcomes; after that, you’re paying in prompt length, latency, and maintenance.
What to do when ambiguity is unavoidable
Sometimes you can’t remove ambiguity because the work itself is underspecified: a fuzzy brief, an evolving strategy, or missing data you can’t access yet. In those cases, force the ambiguity into the open. Ask the model to list its assumptions first, then produce two or three versions that reflect different reasonable interpretations (for example: “executive skim,” “team plan,” “risk-first”). That costs extra tokens and time, but it’s cheaper than polishing the wrong draft.
When stakes are high, add a “safe failure mode”: if a key detail is unknown, the model must say “not provided,” avoid specifics, and return a short set of clarifying questions. You’re not eliminating uncertainty—you’re controlling where it shows up.