Why correct answers can still mislead you
You’ve likely seen a demo where an AI answers confidently and correctly across a dozen prompts, and it’s natural to conclude it “gets it.” The trap is that correctness is an outcome, not an explanation. A system can land on the right answer by leaning on surface cues: common phrasing, familiar templates, or correlations that happened to hold in its training data.
That matters because the same shortcut can break quietly. A résumé screener might “learn” that certain schools correlate with past hires, or a support bot might mirror the tone of a known issue and guess the standard fix. Both can look accurate until the context changes, and then performance drops in ways that feel surprising because the earlier wins looked like understanding.
What people usually mean by “AI understanding”
In day-to-day use, “understanding” usually means something closer to dependable behavior than to human-like insight. People expect the system to track what the question is really asking, keep its interpretation stable across small wording changes, and use the right facts or steps for the right reasons. If you ask it to explain its answer, you want an explanation that matches the work it actually did, not a plausible story.
They also expect transfer: if the format changes, the system should still recognize the same underlying problem. A forecasting model that works only when last quarter looks like the training set doesn’t feel like it understands the business; it feels like it memorized a period. Many tasks don’t come with a clean definition of “the real reason,” so we end up judging understanding by how well performance holds up under slight shifts, adversarial rephrasings, and new examples.
How predictions can be right for the wrong reasons
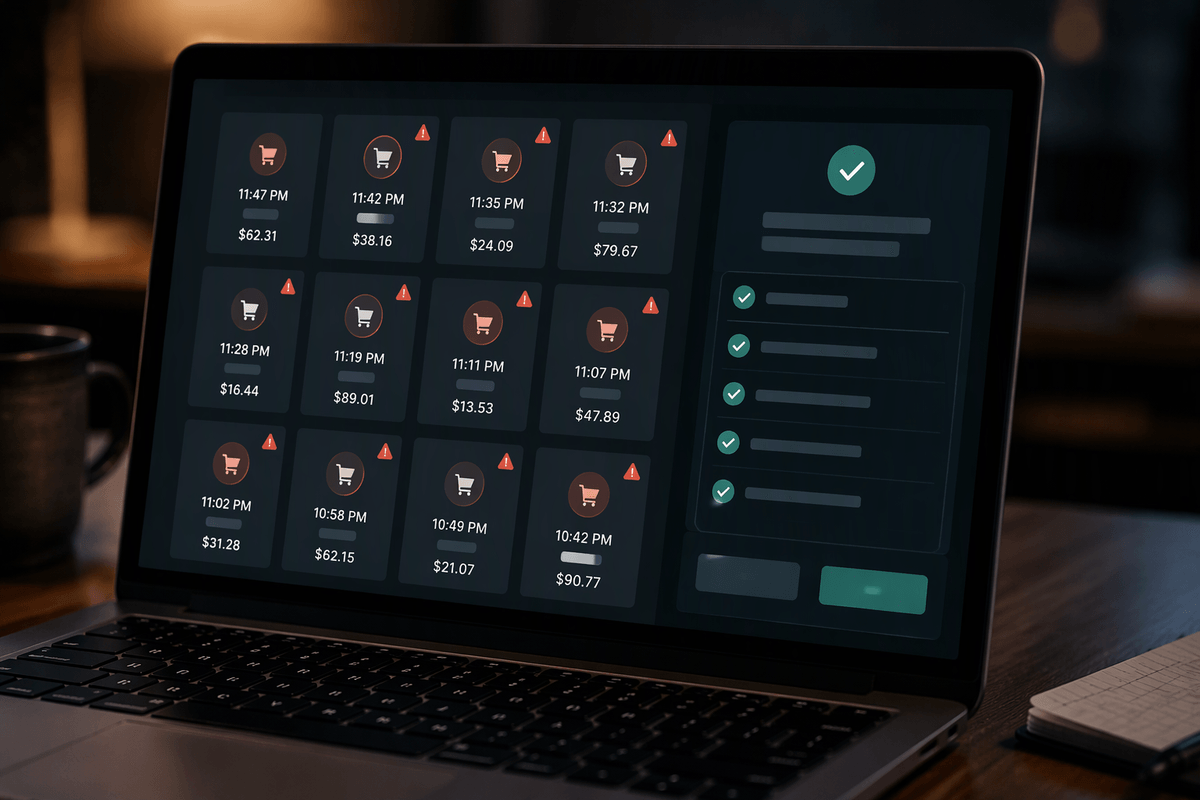
Consider a model that flags fraudulent transactions with impressive accuracy. If most fraud in the training data happened at odd hours and involved a few merchant categories, the model can “solve” the task by keying off time-of-day and category patterns rather than anything about intent or deception. It will look great on a test set drawn from the same period, and it will even produce confident explanations about “suspicious behavior” that sound reasonable to a reviewer.
This is shortcut learning: the system picks the easiest signals that correlate with the label, not the signals you would rely on if those correlations disappeared. The same thing happens in text tasks when an AI learns that certain words, formatting, or even the presence of citations tends to accompany a particular answer. It’s often expensive and slow to discover these shortcuts, because you need targeted tests and manually curated counterexamples rather than more of the same benchmark prompts. Until you do, a high score mainly tells you the model predicts well under familiar conditions, not that it is using the right structure of the problem.
When the world shifts, “understanding” gets tested
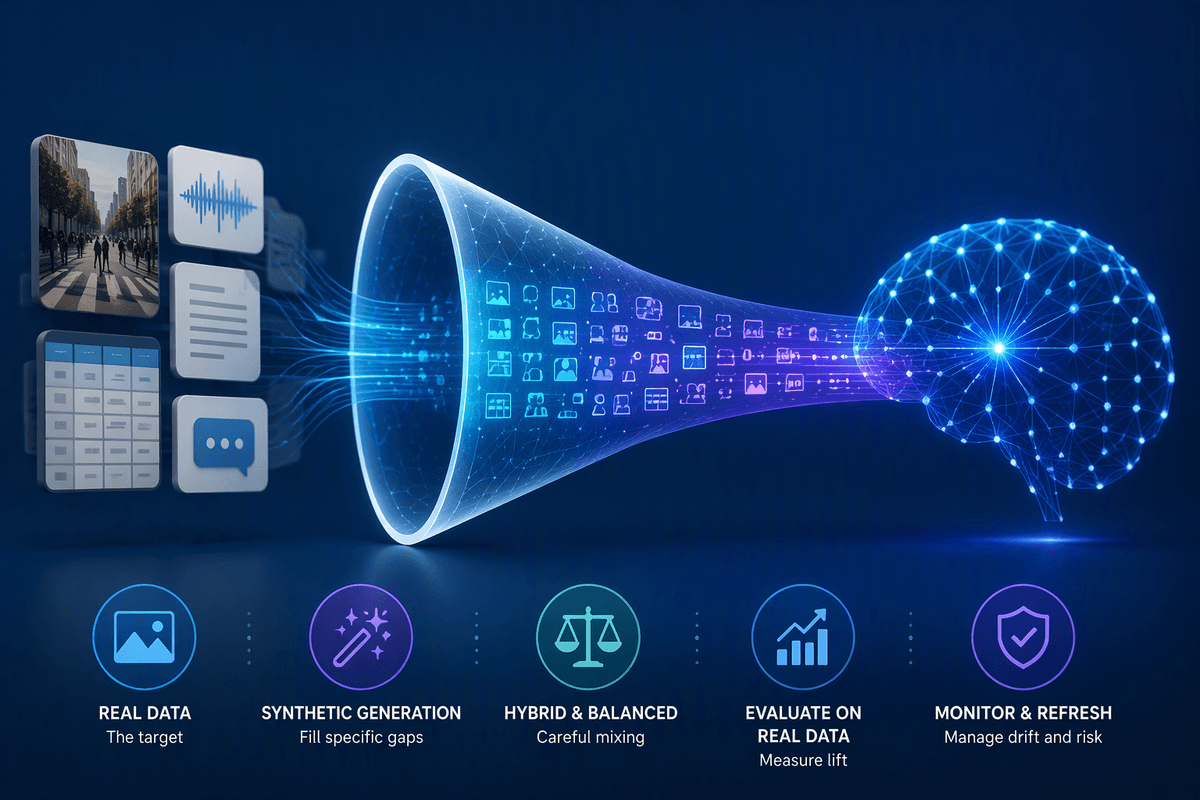
A familiar moment: the model that looked rock-solid in a pilot starts slipping after a product change, a new policy, or a market swing. The wording of tickets shifts, customer segments broaden, fraudsters adapt, competitors copy pricing, or a new regulation changes what “compliant” means. None of that is exotic; it’s ordinary drift. What surprises teams is how quickly “high accuracy” can turn into confident misses when the cues the model leaned on stop lining up with reality.
This is where claims of “understanding” get tested, because a system that truly tracks the underlying structure should degrade more gracefully. It might become less certain, ask for missing context, or fall back to a simpler but safer rule. A shortcut-driven system often does the opposite: it stays confident while being wrong, because it cannot tell that the world has moved. Catching this early usually requires ongoing monitoring, fresh labeled examples, and periodic re-testing—work that is easy to underfund once the demo is over.
Checks that separate competence from comprehension
A recognizable pattern is the model that stays impressive until you change something that “shouldn’t matter”: reorder the facts in a brief, swap neutral synonyms, or ask the same question in a different format (table instead of prose, bullet points instead of a paragraph). Competence often survives one phrasing; comprehension shows up as consistency across many equivalent framings. A basic check is invariance testing: create small, meaning-preserving edits and see whether the answer, confidence, and cited evidence remain stable. When results swing, you’ve learned something concrete about what the system is actually sensitive to.
Another check is counterfactual probing: hold the story constant but flip one key causal detail, then watch whether the conclusion flips for the right reason. In business terms, if a forecast changes, can the model articulate which driver moved and in which direction, and does that track a simple sensitivity analysis? For classifiers, you can use “contrast sets” where two examples differ only in the feature that should matter. These tests cost time because you have to design them; they also reveal uncomfortable gaps, which is exactly why they’re useful before deployment.
A final filter is graceful failure. Ask the model questions that are underspecified or outside policy, and check whether it asks for missing inputs, flags uncertainty, or refuses. Systems that “understand” their limits don’t just answer less; they fail in ways your process can manage.
The temptation to anthropomorphize a strong model
You can feel the pull to treat a strong model like a colleague because it behaves like one: it remembers prior turns, uses hedging language, and produces explanations that read like deliberation. When it answers a messy question with a tidy rationale, it’s easy to assume there is an internal “mental model” matching the story it tells. But the explanation is often another output prediction, optimized to sound coherent, not a window into the mechanism that produced the answer.
Anthropomorphizing shows up in small choices: letting it “use judgment” without defining criteria, accepting confidence as self-knowledge, or assuming it will notice what a careful reviewer would. That’s how teams end up delegating risk decisions to style. The stronger models also create stronger illusions; their failures can be rarer but more costly, because they surface late and can be hard to spot in prose that looks responsible.
Using AI responsibly without assuming it understands
You can treat a model as a powerful autocomplete and still get real value: draft options, summarize documents, extract fields, and propose analyses—while keeping the decision boundary with a human or a simpler rule. Make the contract explicit: what inputs it may use, what it must cite from provided context, what it must not infer, and what triggers “stop and escalate.” Then validate in the environments you’ll actually face: new templates, new segments, adversarial wording, and missing data.
The operational discipline is unglamorous. You need logging, spot checks, and a way to measure drift without waiting for a major incident. Build workflows where the model’s output is easy to challenge: show supporting passages, expose uncertainty, and require structured rationales that can be audited. The cost is ongoing review time, but it’s cheaper than trusting fluency as understanding.