Why high benchmark numbers feel so convincing
You see a chart with a bold “+25%” and a single score that ranks products from best to worst. It feels like clarity: one number that collapses a messy decision into an easy pick. Benchmarks also borrow credibility from their format—repeatable tests, standardized datasets, and tables that look like lab results—so they read as objective even when the setup is highly selective.
High scores are especially persuasive because they map to a familiar story: faster is better, newer beats older, and “state of the art” must be safer to buy. Under deadline pressure, a top-line number becomes a shortcut for risk management, even though it rarely reflects your traffic patterns, your data, or your cost ceiling.
What a benchmark score actually measures (and what it skips)
Picture a benchmark as a very specific obstacle course: it measures how well a system performs on that course, under those rules, with that timing method. The score usually reflects one or two primary outcomes—accuracy on a fixed test set, frames per second on a scripted scene, transactions per second on a canned workload, tokens per second under a particular prompt format. It also bakes in choices about batch size, input lengths, warm vs cold starts, caching, quantization, and even which errors “count,” so the number is inseparable from the configuration.
What it often skips is the mess you actually operate in: p95 and p99 latency during spikes, tail errors, mixed request sizes, multi-tenant contention, IO bottlenecks, retries, and throughput drops when memory is tight. Benchmarks may ignore setup overhead, model loading time, safety filters, or the cost of achieving the score (special hardware, tuned kernels, larger instances). Treat the number as “best case for this recipe,” not a guarantee for yours.
When “top score” is really a dataset match
A common reason a “best-in-class” result fails to generalize is that the test set quietly resembles the winner’s strengths. If you evaluate a retrieval system on questions that look like its training queries, or measure an LLM on benchmarks dominated by short, clean prompts, you may be seeing overlap in style, domain, or difficulty rather than broad capability. Even without intentional gaming, teams iterate against the same public leaderboards for months; the model becomes tuned to that distribution in ways that don’t show up until your inputs shift.
The mismatch shows up in familiar ways: your customer tickets include messy formatting, longer context, jargon, and edge cases the benchmark barely contains. The “top scorer” can still be the right choice, but only if the benchmark resembles your reality. The practical constraint is time and access: building a representative test set takes effort, and some vendors won’t let you run your own data without a procurement step.
Hidden tradeoffs: accuracy wins, but costs rise
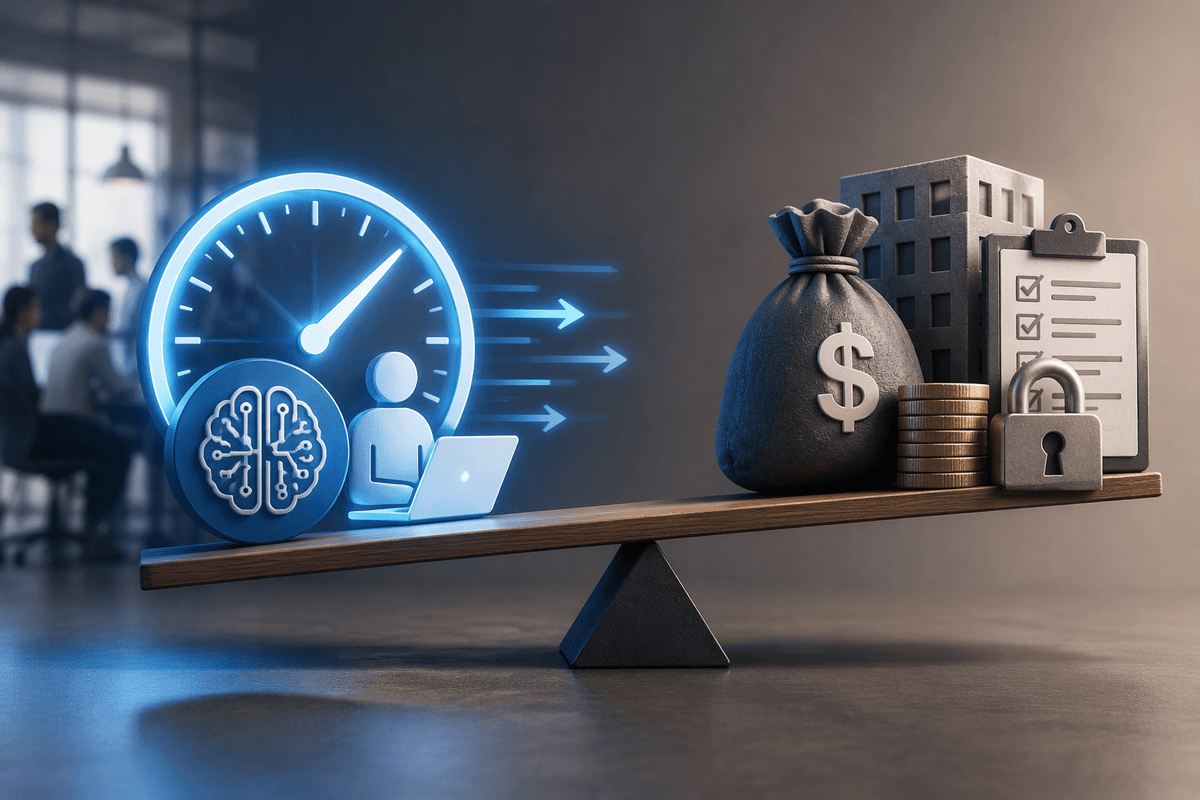
You run a quick pilot and the higher-scoring option does look better on your acceptance set, but the bill and the operational friction climb at the same time. That “last mile” of benchmark accuracy often comes from heavier ingredients: larger models, higher precision, longer context windows, bigger batch sizes, more aggressive ensembling, or more expensive accelerators. Each can raise memory pressure, slow cold starts, and push you toward larger instances just to stay stable under peak load.
The tradeoff hides because most benchmark charts report a single quality number, not quality per dollar, quality per watt, or quality at p95 latency. A model that wins by 2 points on a static test set can still lose in production if it adds 120 ms to the tail, forces you to shard across more GPUs, or raises per-request cost enough that you have to cap features or rate-limit. The decision is rarely “best score,” it’s “best score at the cost and latency you can actually sustain.”
How benchmark chasing can create brittle systems
A familiar pattern is a team that keeps tweaking until the score climbs: special prompt templates, hand-tuned preprocessing, fixed input lengths, and caching strategies that assume repeated queries. These choices can be perfectly valid for the benchmark, but they narrow the operating envelope. In production, requests arrive with messy formatting, unexpected languages, longer contexts, and shifting topics, and the “winning” setup can fall apart in ways the score never exposed.
Brittleness also shows up as hidden coupling to the test harness. You might over-optimize batch size, pin threads, or select precision modes that look great in a clean run, then discover the system becomes unstable under mixed workloads, background jobs, or multi-tenant contention. The practical cost is ongoing: every upstream change (new product feature, new data source, model update, driver revision) risks breaking the tuned recipe, and you pay for regression testing and rollbacks instead of shipping.
A practical checklist to validate the score for you
Benchmark scores rarely provide enough information to justify a purchase or deployment decision on their own. Start by identifying what the benchmark measures: accuracy, throughput, latency, or a combination of these. Then connect the results to your actual requirements, such as p95 latency under peak traffic, sustained throughput, or cost per completed task. Ask for the full test configuration, including hardware, batch size, input lengths, precision, caching, warm-up procedures, and post-processing. Without these details, a high score is difficult to reproduce or compare fairly.
Next, test the system against a representative sample of your own workload. Include realistic complications such as long contexts, inconsistent formatting, multilingual text, and imbalanced classes. Run repeated trials to measure variation rather than relying on the best result from a single run. Check p95 and p99 latency, error rates under load, and performance when memory is constrained or several users compete for resources. Finally, translate the findings into a metric that supports the decision, such as quality at a fixed cost or cost at a defined quality level, with an explicit service-level agreement. When a vendor will not provide access for testing, treat its benchmark claims as preliminary until they can be evaluated in a sandbox or during procurement.
Use benchmarks as a starting point, not the verdict
You still want benchmark numbers, because they narrow the field and expose obvious weak options. The mistake is letting a leaderboard decide the last mile. Treat a score like a hypothesis: “this setup might work well for us,” not “this will work well for us.” Then confirm it against your acceptance set, your traffic shape, and your non-negotiables: p95/p99 latency, error rates under load, cost per task, and operational overhead.
When two options are close, prefer the one that stays predictable across configurations and reruns, even if it gives up a small peak score. A model that is slightly worse on a chart but easier to reproduce, cheaper to operate, and less sensitive to input length or batching usually wins over time, because it leaves room for growth without constant retuning.