Why “step by step” feels like understanding
You’ve probably noticed how a messy answer becomes convincing the moment it’s broken into numbered steps. The structure looks like work: assumptions, moves, and a conclusion that seems earned. For busy readers, that format also matches how we learned in school—show your work, get partial credit, trust the method.
But “step by step” can create the feeling of understanding even when the steps don’t actually constrain the result. A model can produce a fluent path that merely resembles reasoning, with each sentence sounding locally plausible. The practical catch is time: longer explanations cost more tokens and attention, yet still may not make the final answer more reliable.
The plain-language meaning: intermediate steps, not magic
In plain language, “step by step” usually means “include intermediate steps a person can read,” not “reveal a hidden engine of logic.” It’s the difference between getting an answer and getting a worked example: you see the inputs being combined, the unit conversions, the small sub-claims that lead to a final claim. That’s useful because it exposes where you might disagree, and it lets you reuse the method on a similar problem.
It also sets a boundary. Intermediate steps are still just text the model produces, and text can be arranged to look orderly even if it’s loosely connected to the conclusion. On easy tasks, the steps may be redundant. On hard tasks, they can be incomplete, wrong, or selectively detailed. You’re paying for readability, not a guarantee that the model followed those steps internally.
What’s happening inside: tokens, patterns, and search
Open up the hood and you don’t find a little accountant laying out premises and deductions. You find a system that predicts the next token—roughly, a chunk of text—based on the tokens already on the page. Those predictions are shaped by patterns learned from a large training set: how explanations are usually phrased, what steps typically follow “first,” and what conclusions tend to appear after certain kinds of setup.
That’s why “step by step” works as a steering wheel. The prompt nudges the model toward a genre of writing where intermediate statements are common, and that extra structure can reduce simple mistakes by keeping relevant details “in view” as text. But the same mechanism also means steps can be decorative: if the model starts drifting toward a wrong path, it can keep generating plausible-looking continuations anyway. When tools are involved—like retrieval, calculators, or code execution—there may be actual search and checking. Without them, “search” mostly means scanning its learned associations, not looking facts up.
When step-by-step helps—and when it misleads
Think about the last time you asked a model to compare vendors, estimate a budget, or work through a probability question. Step-by-step can genuinely help when the task has dependencies you can inspect: unit conversions, constraints, edge cases, or a plan that must be consistent across multiple sub-answers. The visible steps act like a checklist. You can spot a wrong assumption early, notice a missing variable, or see that a conclusion doesn’t follow from the numbers given.
The trap is that the same format also improves “believability” for answers that aren’t anchored to anything. Models can generate a clean rationale after they’ve already drifted to a conclusion, or fill gaps with invented facts that sound like typical supporting details. This shows up in citations that don’t exist, confident math with a quiet arithmetic error, or legal and medical explanations that match the tone of expertise but not the actual rules. Longer chains can even make this worse by giving more places to hide a mistake, while also costing more tokens and review time.
Hidden reasoning vs shown reasoning: the safety trade-off
There’s another wrinkle: the steps you see aren’t necessarily the steps the model “used.” Many systems generate internal scratchwork and then produce a cleaner explanation meant for readers. That separation matters because verbose, uncensored chains can leak things you don’t want: private details echoed from the prompt, guessed personal data, or procedural guidance that makes harmful requests easier to carry out. They also give attackers more surface area for manipulation, because a model that narrates its deliberation can be steered into revealing policies, shortcuts, or sensitive intermediate content.
Hiding that scratchwork improves safety and privacy, but it removes a crutch people rely on to build trust. You get an answer without the “show your work” comfort, and you can’t tell whether the model checked anything or just wrote a plausible story. The practical trade-off is that safer outputs often shift the burden to you: you may need to ask for a short justification, explicit assumptions, and a separate verification step—which costs time, tokens, and attention.
Better alternatives: checks, tools, and verifiable work
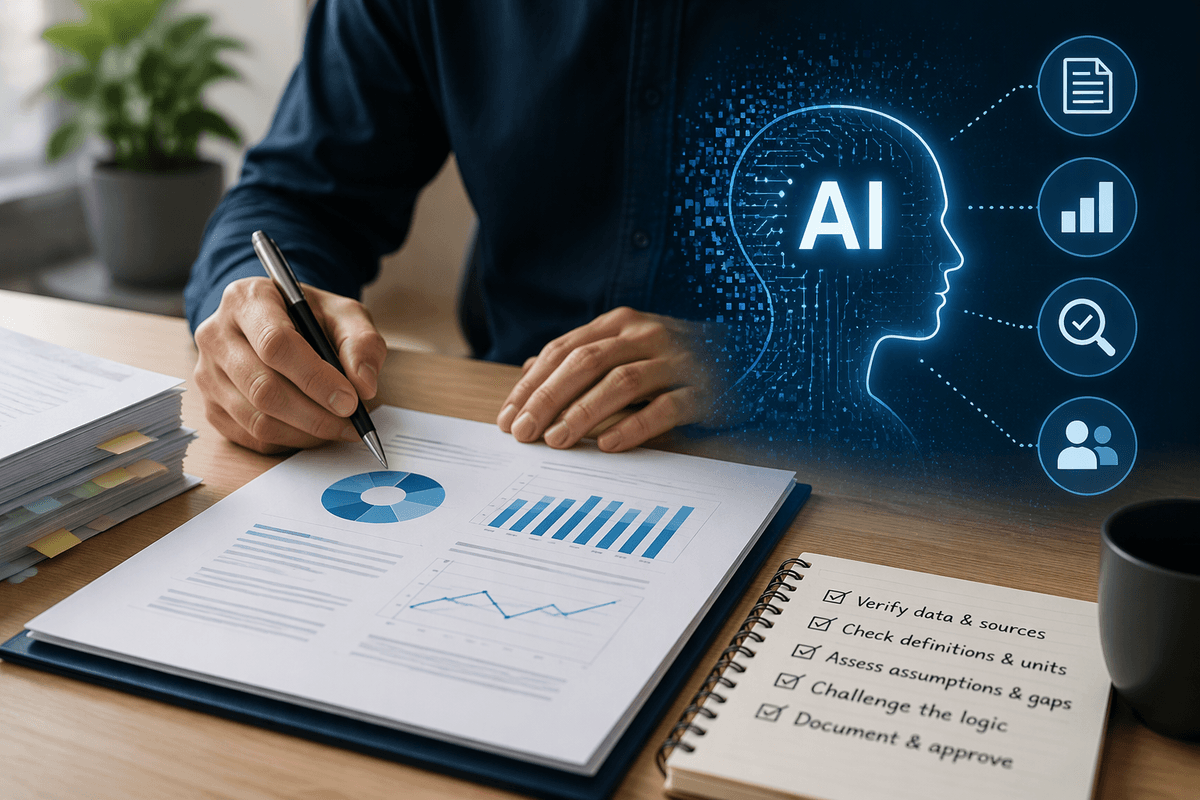
A more dependable pattern is to treat the model like a draft generator and make the “work” something you can independently validate. Ask for explicit assumptions, a short list of variables, and a final answer formatted so you can audit it: a table, a formula, or a numbered set of claims you can check one by one. Then request a separate pass that only does verification: “Check units,” “recompute the arithmetic,” “list two counterexamples,” or “name what would change the conclusion.” That second pass is often more useful than a long narrated solution, because it forces concrete failure modes into view.
When the task touches facts, numbers, or rules, lean on tools that produce artifacts. Use a calculator or code execution for math, spreadsheet-style breakdowns for budgets, and retrieval for “what does this document say?” rather than “what do you remember?” For policies and contracts, have it quote exact clauses you provided and map conclusions back to those excerpts. The practical drawback is friction: tool access, setup, latency, and sometimes privacy constraints if sensitive data can’t leave your environment. Still, verifiable outputs usually beat elegant prose when accuracy matters.
How to ask for “reasoning” you can trust
You don’t need “reason step by step” as a blanket request; you need constraints. Ask it to state assumptions upfront, define variables, and produce an answer you can audit (a formula, a table, or a numbered list of checkable claims). Separate solving from checking: “Give the answer, then run a verification pass that recalculates, tests edge cases, and flags any step you’re uncertain about.” When facts matter, require sources you provide (a doc excerpt, dataset, or tool output) and have it point to the exact lines it used. Expect some extra cost in tokens and review time, but buy reliability where it counts.