Why generative AI changes AWS’s growth story
AWS’s growth story used to be straightforward: move servers to the cloud, pay as you go, expand steadily with storage, databases, and analytics. Generative AI changes that math because it pulls spending toward compute-heavy workloads that scale fast once a team finds a use case that “works.” A single internal chatbot can be small; rolling it out to tens of thousands of employees is a different budget line.
It also shifts buying behavior. Customers ask for model performance, data controls, and latency guarantees, not just instances and regions. The inference bills can surprise even well-run teams, so optimization and governance become part of the sales motion, not an afterthought.
Where the new revenue shows up first
The earliest revenue tends to appear in places that look familiar on an AWS bill, even when the project feels new. Teams start by renting more compute for experiments, then add steady inference capacity once a pilot becomes a real workflow. That usually pulls in higher-margin attachments: managed databases for retrieval, object storage for prompts and embeddings, and monitoring tools to track latency, errors, and usage by business unit. Even when the “AI product” is a chatbot, the spend spreads across core infrastructure lines.
Another early signal is services work, whether it’s AWS’s own professional services or partners brought in to make data usable, set up access controls, and define evaluation tests. Many companies discover they can’t scale until they pay down data quality and security gaps, which slows timelines but increases near-term consulting and platform spend.
From chips to chatbots: Amazon’s genAI stack
A recognizable pattern is that a genAI initiative rarely starts with “a platform,” it starts with a team picking a model and trying to make it fast, safe, and affordable. On AWS, that journey maps to a layered stack. At the bottom is specialized compute for training and inference, where instance choice, networking, and storage throughput can matter as much as the model itself. Above that sit managed data services that make retrieval work in practice: durable object storage, databases for application state, and vector search options that keep latency predictable when prompts need company context.
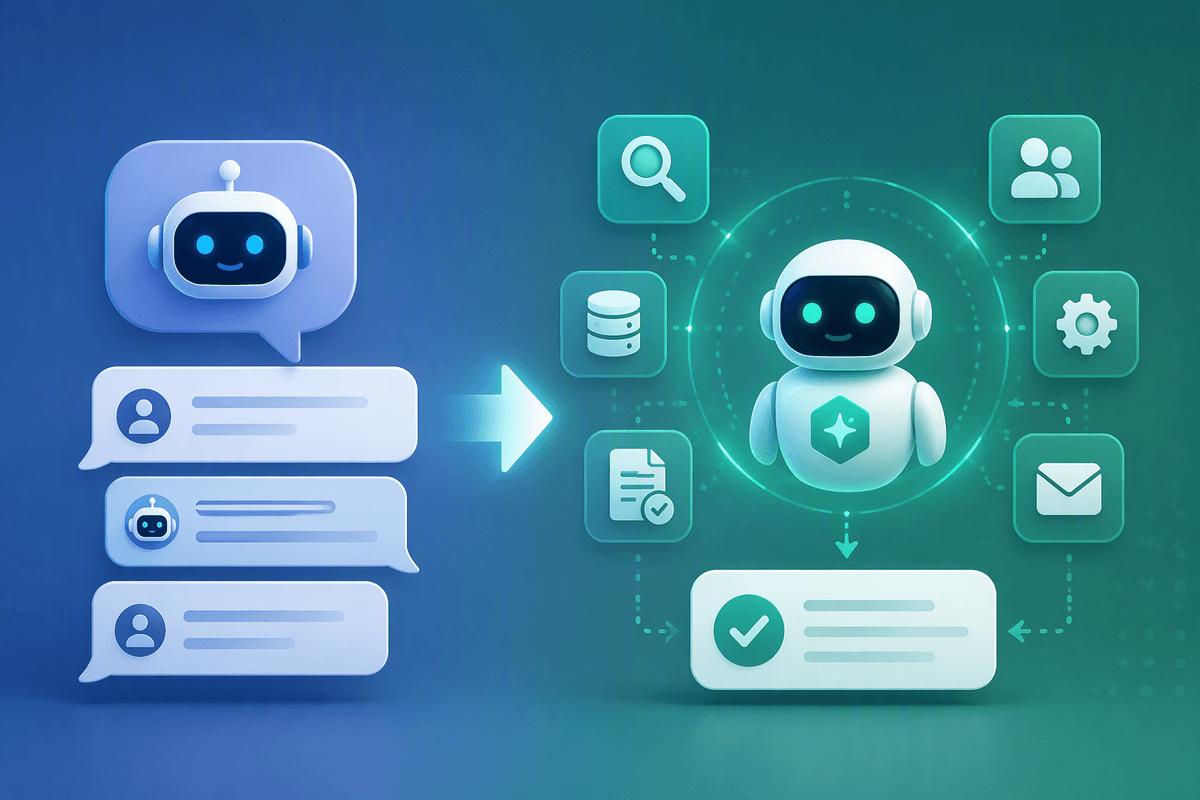
Then the tooling turns infrastructure into a repeatable product motion: model hosting, guardrails, evaluation, and monitoring so a pilot doesn’t collapse under real user volume. Finally, the “chatbot layer” is usually an application built with orchestration, identity controls, and logging that satisfies internal audit. Each layer is owned by different teams, and the bill fragments across services, making optimization and accountability harder than a single, bundled SKU.
Bedrock’s “model choice” bet versus lock-in
A common enterprise worry is swapping one dependency for another: moving from a single model provider to a single “AI platform” that quietly dictates which models, tools, and pricing you live with. Bedrock’s positioning leans into that anxiety by emphasizing model choice—first-party and third-party options behind a consistent API—so teams can change models without rewriting the whole application stack. That matters when performance shifts quickly, or when legal and procurement teams change their risk posture midstream.
The platform convenience still creates gravity. Once you build around Bedrock’s identity integration, logging, guardrails, evaluation hooks, and managed retrieval patterns, the hard part to move isn’t the model call, it’s everything around it. Even if the API surface is portable in theory, the operational footprint is not. The practical decision is to treat “model choice” as a hedge, not an exit plan, and to design for swap tests early while the system is still small.
What enterprises need before they scale genAI
Most enterprises don’t fail at genAI because they picked the “wrong” model; they fail because the surrounding plumbing can’t handle real usage. Before rollout, teams need a clear data boundary (what the model can and cannot see), clean retrieval inputs, and a way to prove that answers are grounded in approved sources. That means identity-aware access controls, logging that ties prompts to users and business units, and an evaluation loop that catches regressions when prompts, documents, or models change.
The operational bar is higher than a typical SaaS pilot. Finance needs showback so experimentation doesn’t become an open-ended inference bill, and engineering needs rate limits, caching, and fallback behaviors when latency spikes or a model call fails. Security and legal need policy-as-code guardrails and a path for audit requests, not ad hoc screenshots. These requirements pull in platform, security, data engineering, and procurement at the same time, and most companies don’t have that bandwidth unless the use case has a defined owner and a measurable ROI target.
Competitive pressure and the risks to watch
A familiar moment: you run a bake-off, and the “best” cloud depends less on raw model quality and more on where your data, identity, and developer workflow already live. Microsoft’s advantage is tight coupling to Microsoft 365 and Azure governance patterns; Google’s is research depth and data tooling. AWS’s counter is breadth—multiple model options, a deep infrastructure catalog, and the promise that cost can be engineered down with instance choice, caching, and architecture.
Price pressure will show up first in inference, where enterprises will demand predictable unit economics and may pit vendors against each other every renewal. Model choice can fragment operations, with different latency, safety behavior, and logging requirements per model. Security posture is also a moving target: prompt injection, data leakage through retrieval, and “shadow AI” usage can outpace controls. Finally, watch concentration risk: even without model lock-in, dependence can shift to proprietary orchestration, guardrails, and monitoring that are expensive to unwind.
How to interpret Amazon’s genAI expansion signals
The clearest expansion signals are boring ones: rising spend in compute and data services tied to steady inference, plus higher attach rates for monitoring, security, and governance. Treat packaged announcements as secondary; the leading indicator is whether AWS makes it easier to control unit cost per query through better instance economics, caching patterns, and pricing that finance can forecast. Watch partner activity and migrations into Bedrock-like primitives, because that’s where operational lock-in forms even when models stay swappable. A practical constraint remains talent: if AWS’s tools reduce cross-team coordination work, adoption accelerates; if not, pilots stall despite hype.