Why “agent” isn’t just a fancier chatbot
If you’ve used a customer-support chatbot, you’ve seen the pattern: you ask, it answers. Even when the answers are good, the interaction usually ends at advice, a draft, or a suggestion. It stays inside the conversation and depends on you to take the next step.
An “agent” is different because it’s designed to complete a task, not just talk about it. That typically means it can choose actions (like calling internal systems, searching a knowledge base, creating tickets, updating records) and keep track of what it’s doing across steps. The trade-off is practical: more moving parts, more permissions, higher monitoring and testing costs, and more ways for mistakes to show up as real-world changes.
From answering questions to completing real tasks
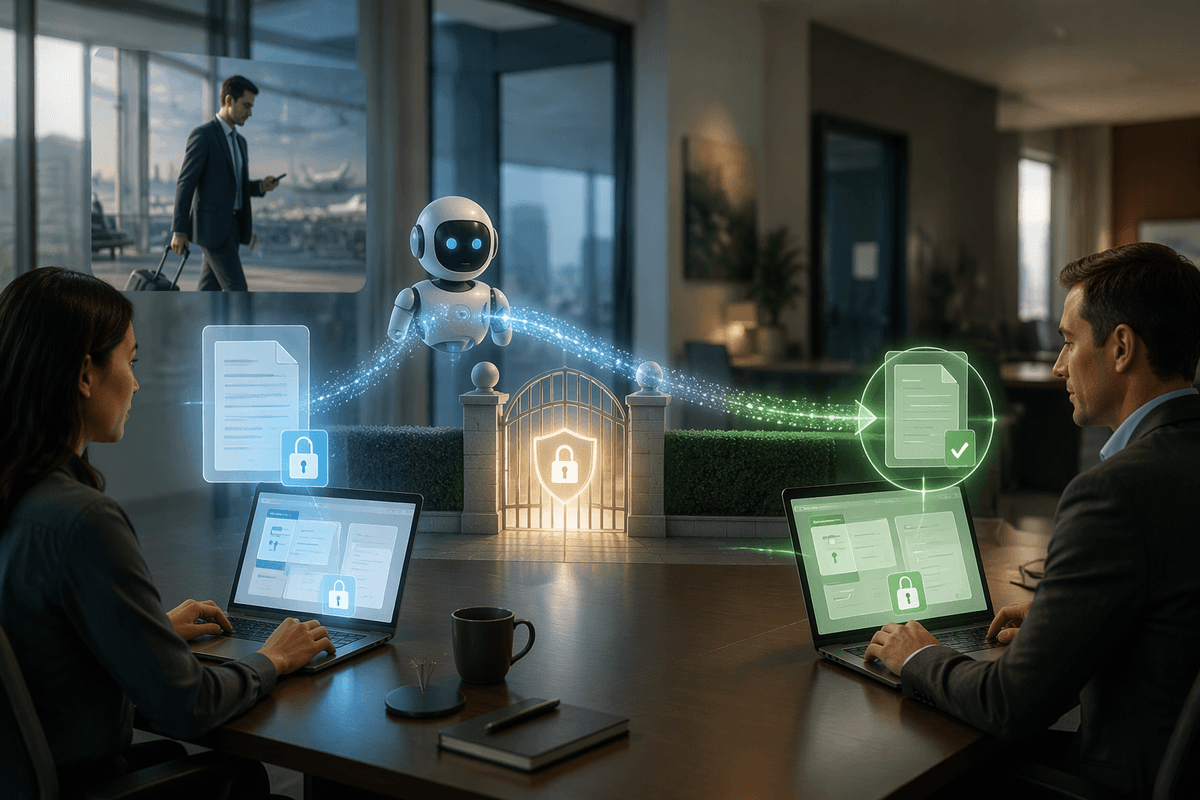
Picture a common workflow request: “Can you help onboard this new vendor?” A chatbot can explain the steps, summarize the policy, and draft the email to procurement. An agent is expected to move the work forward: collect the required fields, check the vendor against an internal list, open the onboarding ticket, attach the documents, and notify the right approver—often in the correct order and with the right constraints.
That shift matters because “doing” requires access to tools and systems, and it requires handling partial progress. If an API call fails or an approver is out of office, the agent has to retry, route around the block, or stop safely and ask for input. You also have to decide what it’s allowed to change, what must remain read-only, and what needs confirmation. Those guardrails add implementation time and ongoing operational cost, but they’re what separates a helpful conversation from a reliable task runner.
How agents choose actions and use tools
In practice, an agent spends as much time deciding what to do as it does generating text. Given a goal like “onboard this vendor,” it breaks the request into steps, picks the right tool for each step (a form intake, a vendor database lookup, a ticketing API, an email sender), and checks whether it has enough information to proceed. When it doesn’t, it asks targeted questions because guessing a tax ID or approver is worse than being slow.
Tool use also forces the agent to confront reality: inputs must match a schema, APIs time out, and systems disagree. A well-designed agent uses “cheap” checks first (validate fields, confirm policy constraints, read current status) before taking irreversible actions (creating records, issuing refunds, changing access). Many teams add explicit decision points—“draft vs send,” “create vs update,” “needs approval”—so the agent can pause for confirmation. The cost is extra plumbing and telemetry: you need logs of tool calls, retries, fallbacks, and clear error handling, or the agent becomes hard to trust and harder to debug.
Memory, state, and goals that persist
You’ve likely seen a chat experience “forget” what mattered: you confirm the billing account, then two messages later it asks again, or it drafts an email that ignores the decision you just made. That’s not only annoying; it’s a sign the system is mostly treating each turn as disposable text. Agents, by contrast, need working memory and state because tasks span steps, time, and systems. They track what’s already done (ticket created, documents attached), what’s pending (approval request sent), and what’s blocked (missing W-9), so they don’t loop or redo work.
Persistent goals also change how you design the experience. You need to define which facts can be stored, for how long, and where they live: in a session record, a workflow object, or an auditable log. This adds complexity and real cost. Storing the wrong thing can create privacy risk, while storing too little makes the agent unreliable and forces users to repeat themselves.
Autonomy: the upside and the new risks
The appeal of autonomy shows up when nobody wants to “babysit” the workflow. If the agent can watch for a missing W-9, nudge the vendor, re-route to a backup approver, and keep the ticket moving, you get shorter cycle times and fewer handoffs. Done well, it also reduces the mental load on operators because the agent carries the checklist, remembers the last known state, and only escalates when a decision is genuinely needed.
The same autonomy is where the risk profile changes. A chatbot that’s wrong wastes time; an agent that’s wrong can create duplicate records, notify the wrong people, or apply a policy exception that becomes hard to unwind. The failure modes also get sneakier: tool permissions that are too broad, “helpful” retries that spam systems, or subtle data leakage when the agent stores more context than it should. Mitigations aren’t free—approval gates, least-privilege access, sandbox environments, and human review add latency, engineering effort, and ongoing monitoring.
When a traditional chatbot is the better fit
Sometimes the simplest product is the safer product. If the user’s job is primarily to understand, decide, or communicate—“What’s our travel policy?”, “Summarize this contract clause,” “Draft a reply to this customer”—a traditional chatbot is often the better fit because the output is naturally reviewed before anything changes. You get value without wiring up APIs, permissioning, retries, and audit logs, and you avoid the awkward question of who “authorized” an action that happened silently in the background.
Chatbots also win when the ground truth is fuzzy or the downside of being wrong is high. Early-stage processes, exceptions-heavy workflows, and areas with shifting rules (pricing, compliance interpretations, edge-case refunds) tend to benefit from assisted thinking, not autonomous execution. A chatbot can surface options, ask clarifying questions, and produce a structured plan while leaving the final call and the system updates to a human.
The practical test is friction: if you’d still require a confirmation click for every meaningful step, you may be paying agent-level complexity for chatbot-level outcomes.
A practical checklist for choosing chatbots vs agents
Start with the outcome you’re buying: do you need a high-quality response, or a completed change in a system? If it’s “inform and draft,” prefer a chatbot; if it’s “move work forward,” consider an agent only when the task has clear steps, stable rules, and reliable APIs. Map what the model must touch (create, update, delete) and require explicit confirmation before irreversible actions like refunds, access changes, or external sends. Budget for the unglamorous parts: permissions design, audit logs, retries, monitoring, and incident response. If you can’t specify success criteria and rollback, keep it conversational.