Why teams turn to synthetic data
Teams turn to synthetic data when the real thing is scarce, slow, or risky to use. A fraud model may have few confirmed positives, a medical model may face strict access controls, and a customer-support model may rely on logs that can’t be freely shared across teams. Even when data exists, labeling can be the bottleneck: edge cases are rare, experts are expensive, and policies can limit what annotators can see.
Synthetic data promises faster iteration by filling gaps, balancing classes, and generating controlled scenarios that are hard to capture naturally. The trade-off is practical: it costs time to design generators and validate realism, and the model can learn the generator’s quirks instead of the world.
What counts as synthetic data in training
Synthetic data in training is any example whose inputs, labels, or both are produced by a process other than direct measurement of the real world. That includes classic augmentation (cropping images, adding noise, paraphrasing text), as well as “label synthesis,” where humans provide inputs but labels come from rules, weak signals, or a teacher model. It also includes fully generated records from probabilistic models, diffusion models, or LLMs that create prompts, conversations, or structured rows designed to mimic production data.
Simulation sits in the same bucket when you train on outputs from a game engine, physics model, or agent-based environment rather than logged events. The boundary that matters isn’t whether it looks realistic, but whether the generation process can drift from your deployment distribution. The cost is that every synthetic source adds an extra system to maintain: prompts change, simulators get tuned, and “small” shortcuts can become training signal.
Where synthetic data fits in the pipeline
Synthetic data is most useful when it is treated as a controllable ingredient rather than a replacement for production logs. Early on, it can unblock prototyping: you can validate feature pipelines, model architectures, and training code paths before data access and labeling are fully solved. It also fits naturally around the labeling step—either by generating hard negatives and rare positives to balance a dataset, or by synthesizing labels (rules, heuristics, teacher models) to turn cheap inputs into training signal.
Later in the lifecycle, synthetic data tends to work best as targeted supplementation. Teams use it to increase coverage of scenarios that matter operationally—new product flows, policy-driven edge cases, or failure modes discovered in evaluation—then mix it with real examples to keep the model anchored. The practical constraint is evaluation: the only reliable gate is performance on a real-data holdout that reflects deployment, plus checks for shift (are you changing the distribution) and contamination (did synthetic generation leak test-like patterns into training).
Common ways synthetic data is generated
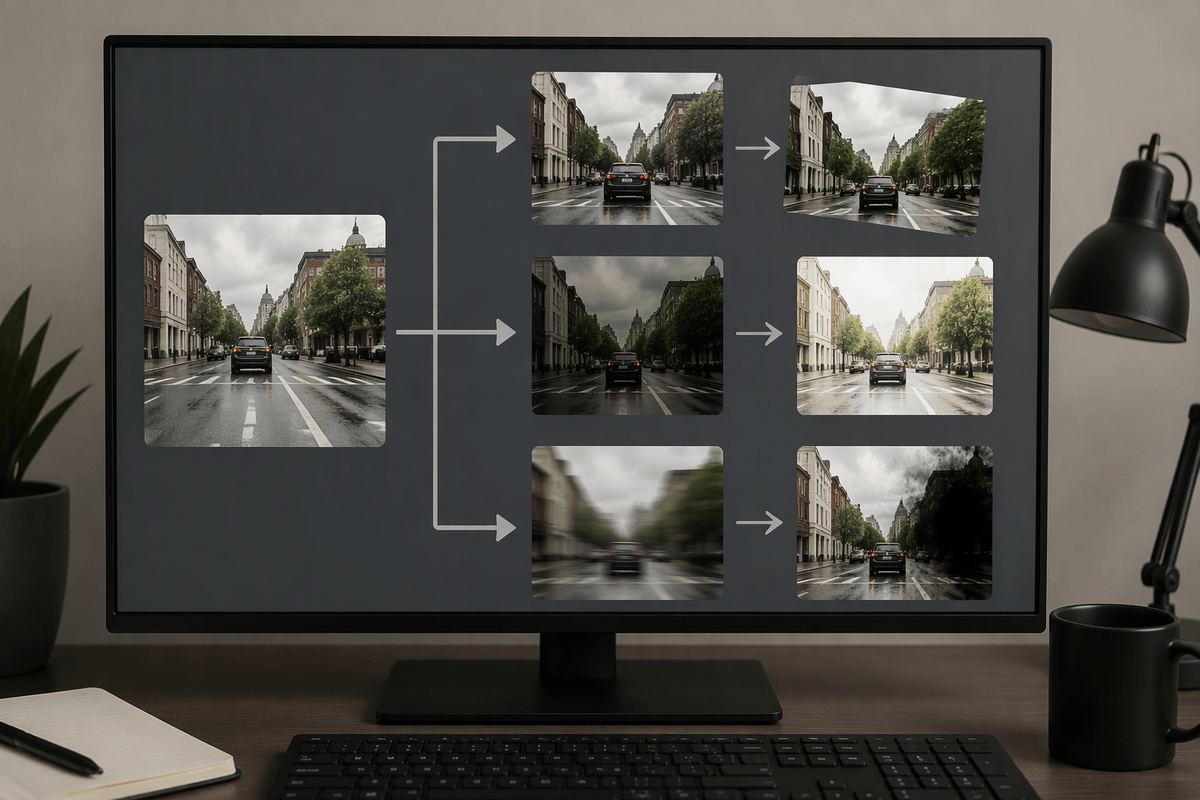
In practice, most teams start with augmentation because it is cheap and easy to reason about. For images, that might mean crops, rotations, lighting shifts, or synthetic occlusions that mimic camera problems. For text, it can be paraphrases, back-translation, template-based rewrites, or controlled perturbations like swapping entities and dates. For tabular data, teams often add noise within business constraints, resample minority classes, or generate “near-miss” negatives around decision thresholds to sharpen a classifier.
When the domain has rules, simulation and procedural generation usually come next. A robotics team can render scenes with a physics engine; a payments team can simulate transaction graphs with known fraud patterns; a logistics team can generate routes under capacity and weather constraints. Generative models also play a role: diffusion models can create images, while LLMs can draft dialogues, support tickets, or synthetic queries paired with “gold” answers. Finally, label synthesis turns real inputs into training data by attaching labels from heuristics, programmatic rules, distant signals, or a teacher model. The constraint across all of these is maintenance: generators, prompts, and simulators drift, and keeping them aligned with production takes ongoing effort.
How to tell if it’s “good enough”
A common failure mode is judging synthetic data by how “real” it looks to humans rather than whether it improves decisions on real inputs. The baseline check is simple: keep a locked holdout of real, recent data that matches deployment, and only accept synthetic additions that improve the metrics you actually ship on (not just training loss). If the holdout is tiny, use repeated splits and report variance; synthetic data that “helps” only in one slice is usually a sign you are fitting noise.
Quality also shows up as coverage and shift. Compare feature distributions between real and synthetic, but don’t stop at averages; look at tails, conditional relationships (for example, label rates by segment), and error profiles by cohort. Then run targeted evaluations on stress tests: rare intents, long-tail entities, extreme amounts, unusual device types. The practical cost is that this requires instrumentation and time: you need checks that catch duplicates, prompt artifacts, or simulator shortcuts, and you may need privacy tests if generation could reproduce memorized rows. “Good enough” is when synthetic data raises real-world performance without narrowing robustness.
Risks: bias, privacy, and overfitting to fake patterns
A familiar pattern is that the model looks better in offline tests, then fails in production for reasons that feel “weird.” Synthetic data can amplify bias by over-representing the scenarios you thought to generate, while under-representing the ones you didn’t. If your generator assumes a “typical” customer, device, dialect, or clinical presentation, the model may become more confident and less fair at the same time. The risk is highest when synthetic data is used to balance classes without also matching how those classes appear across segments.
Privacy is the other quiet trap. If a generative model or teacher has seen sensitive examples, synthetic outputs can echo rare identifiers, phrasing, or unique combinations of attributes. That can happen even when samples look “new.” Practical controls include deduping against real corpora, nearest-neighbor similarity checks, and restricting prompts and conditioning variables that could reconstruct specific rows.
Overfitting to fake patterns shows up as brittle shortcuts: prompt quirks, simulator artifacts, or overly clean labels. Mixing ratios, ablations, and real-data-only evaluation help keep the model anchored, but they add compute and iteration cost.
Choosing a hybrid strategy that actually works
A workable hybrid strategy starts with a simple rule: real data defines the target, synthetic data fills specific gaps. Keep a fixed, recent real-data holdout and treat every synthetic source like a feature: add it, measure lift, and keep it only if it improves the metrics you ship. Build small “challenge sets” from real failures (appeals, escalations, chargebacks, QA audits) and use synthetic generation to expand those patterns, not to replace baseline coverage.
Operationally, manage ratios and drift. Start with low synthetic mixing (for example, 5–20%), run ablations, and monitor segment-level deltas so gains aren’t hiding regressions. Budget time for generator upkeep, privacy checks, and periodic refreshes; otherwise the hybrid approach silently becomes training on yesterday’s assumptions.