Finding AI blogs you’ll actually keep reading
You’ve probably subscribed to a few AI newsletters, skimmed three issues, then quietly stopped opening them. The problem usually isn’t your attention span—it’s that many sources don’t match how you actually use AI at work. Some are great for shipping workflows and prompts, others are better for tracking models and benchmarks, and a third group mostly covers product launches and platform changes. If you don’t separate those needs, every feed feels noisy.
A good “keep reading” shortlist is small and role-driven: one source that reliably teaches repeatable tactics you can try this week, one that summarizes research without pretending every paper is a breakthrough, and one that catches tooling updates that could break or improve your stack. Even 15 minutes a day adds up, so anything that doesn’t earn that time should be cut fast.
Start with your job-to-be-done, not hype
You notice it the moment you open a “must-read” AI post and can’t tell what you’d do differently afterward. Start by naming your job-to-be-done in plain terms: “draft better customer emails,” “speed up SQL analysis,” “reduce support backlog,” or “ship a feature with fewer regressions.” When a blog claims a breakthrough, translate it into an expected work outcome, then look for the missing middle: the steps, inputs, examples, and failure modes that connect the claim to your day-to-day.
This filter protects you from two common time-wasters: content that’s interesting but non-actionable, and content that’s actionable only if you have a very specific stack. A practical source will state assumptions (tools, data access, budget), show a repeatable workflow, and admit trade-offs like latency, cost per run, or review effort. If you can’t imagine running the approach in under an hour, it’s probably hype for your role.
Blogs that publish practical, repeatable AI guides
Practical AI guides move quickly from general ideas to concrete decisions: what data is needed, which tools to use, what successful output looks like, and how to validate the results. Strong how-to blogs read like executable playbooks rather than trend commentary. They include sample inputs, exact prompts or specifications, evaluation checklists, and common failure modes such as fabricated citations, overconfident SQL, or inconsistent tone. This structure makes the advice easier to reuse across different fields while preserving the steps that matter.
When evaluating sources, favor writers who share practical materials rather than opinions alone. Templates, scoring rubrics, prompt patterns, agent workflows, and small reference implementations provide something to test and adapt. Cost and latency figures matter just as much. Claims that a workflow “works great” mean little without knowing whether it costs $200 a day or takes 90 seconds to complete each run. Reliable guidance also explains how to handle failures, when human review is necessary, and how to measure whether automation saves time or merely shifts work to another stage.
One simple test is whether the method can be documented and assigned to a teammate with clear success criteria. Without reproducible steps and a way to evaluate the outcome, the advice remains an idea rather than a repeatable workflow.
Where to follow research without reading papers all day
You’ve likely felt the research gap in a familiar way: a model update ships, your team asks whether it changes anything, and the only “source” you can find is a thread that mixes real results with confident guesses. The trick is to follow interpreters who turn papers into decisions. Look for sources that consistently answer the same questions you’d ask in a review: What problem does this solve better than before? What’s the baseline? What data or evaluation setup was used? What breaks in real use (edge cases, safety, domain shift)? The best research summaries include enough detail to sanity-check the claim without forcing you to open a PDF.
Prioritize outlets that compare approaches across time instead of treating each release as a new era. Leaderboards and benchmark roundups can help, but only if they discuss what the benchmark misses and how results change under different prompts, longer contexts, or tool use. The research coverage often lags or cherry-picks, and it’s easy to overfit your roadmap to a metric. When a summary sounds too clean, treat it as a lead, not a conclusion, and look for at least one independent replication, ablation, or “we tried it and it didn’t generalize” write-up before you bet engineering time.
Best sources for tool updates and ecosystem shifts
Changes to model names, default settings, or pricing tiers can quietly break an established workflow. The most useful sources for tracking these changes are vendor changelogs, release notes, status pages, and API documentation. They identify what changed, when it happened, and which adjustments may be needed. Pair these official sources with one reliable industry publication that follows broader shifts, including adoption of orchestration frameworks, consolidation among vector databases and evaluation tools, and the growing use of open models in production.
Specificity separates useful tooling coverage from launch announcements. Look for migration instructions, backward-compatibility notes, deprecation dates, and concrete examples of new parameters or usage limits. Promotional coverage may highlight new capabilities while overlooking the details that create work during implementation. Updates also require periodic checks of existing prompts, tests, and guardrails, since even a minor change in model behavior may affect a previously stable workflow.
For day-to-day monitoring, follow the official release channels of the two or three tools your work depends on, alongside one source covering broader industry developments. This keeps you informed about changes that matter without spending too much time tracking features you have no plans to adopt.
How to judge quality: signals, bias, and track records
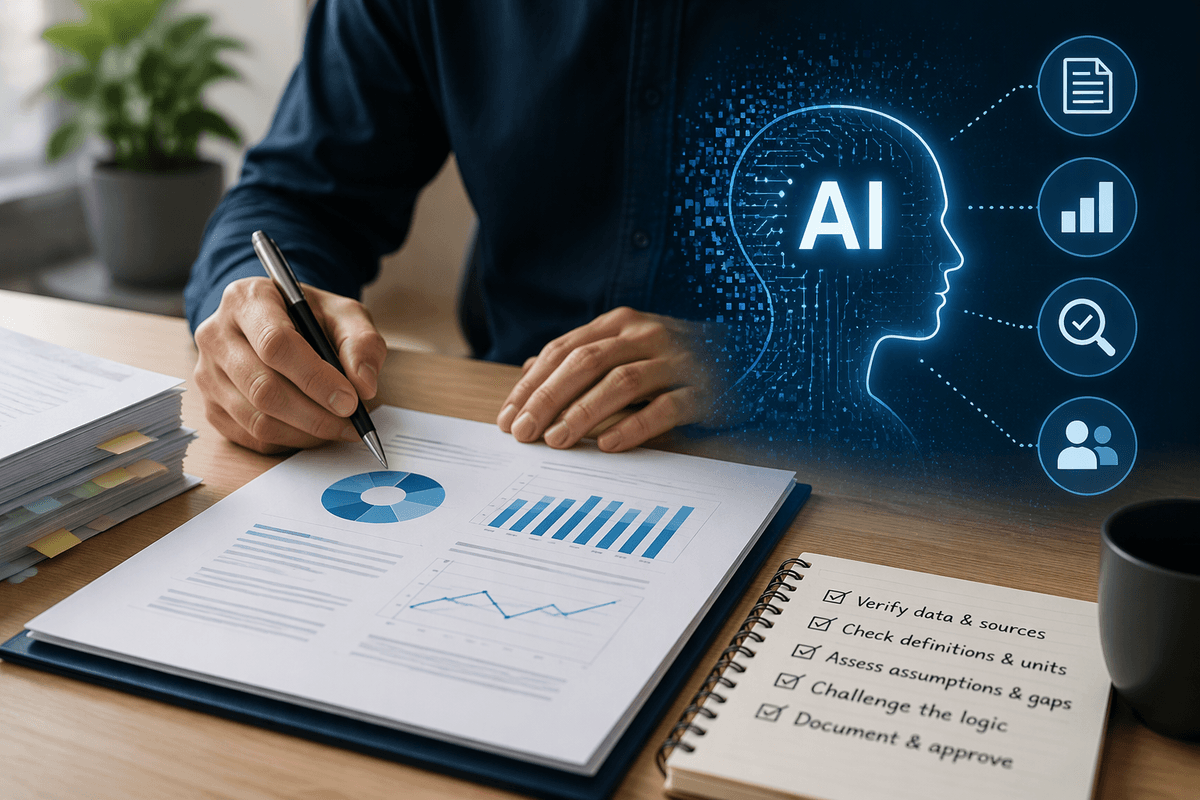
Confident writing, polished charts, and detailed examples do not necessarily make an AI analysis trustworthy. More reliable signals appear in the methodology: the author identifies the model version, data, and tools used, explains how performance was evaluated, and includes negative results or edge cases. Comparisons also need a credible baseline and a clear explanation of why the test is fair. Be cautious with demonstrations built around one carefully selected example, especially when costs, latency, and human review time are left out.
Potential bias is easier to assess when affiliations are disclosed. Affiliate arrangements, vendor partnerships, and close ties to one platform provide useful context, but none automatically invalidates the work. Past recommendations offer a stronger test of credibility. Review several older posts and consider whether their conclusions held up as tools and models changed. Writers who revisit earlier claims, explain where circumstances have shifted, and publish corrections provide a more dependable basis for decisions than sources focused only on new launches.
A low-effort system to keep up weekly
You already know what happens when you “catch up” in big bursts: you read a lot, retain little, and still miss the one breaking change that mattered. A low-effort weekly system works better when it’s scheduled, bounded, and boring. Pick a single inbox or RSS folder called “AI Weekly,” then cap it at 6–10 sources total: 2 practical how-to writers, 2 research interpreters, 2 tooling/update channels, and optional 1–2 domain-specific voices for your industry.
Run a 25-minute review once a week. Save only items that pass two tests: you can name a concrete work decision it affects, and you can restate the setup (tool/model, constraints, evaluation) in one sentence. Everything else gets archived without guilt. The real cost is follow-through, so keep one running doc: “Try,” “Watch,” and “Ignore,” and move at most one item into “Try” per week.
Build your personal AI reading stack over time
You’ll notice your “perfect” stack breaks the moment your work changes: a new product area, a new model provider, or a quarter where reliability matters more than novelty. Treat your reading list like a toolchain. Add sources only when they fill a specific gap, and remove them when they stop doing that job. A useful constraint is a two-week trial: if a source doesn’t produce at least one “Try” item or prevent one avoidable mistake, unsubscribe.
Over time, aim for coverage, not volume. Keep one stable baseline you trust, then rotate a single “exploration slot” for a month at a time. When something earns its place, write down what it’s best for (“prompt patterns for support,” “model behavior notes,” “API breaking changes”) so you’re not re-evaluating from scratch every week.