The moment your agent stops making progress
You notice it first as a change in texture: the agent’s updates get vague, repetitive, or oddly confident without producing anything you can use. In support, it keeps “checking the account” but never returns an answer. In ops, it says it’s “validating inputs” while the ticket stays untouched. In coding, it reopens the same files and re-explains the plan, but no patch appears. The problem isn’t only wasted time; it’s that the user can’t tell whether to wait, intervene, or stop.
That moment matters because most stalls look identical from the outside. A tool call may be failing behind the scenes, a permission may be missing, the context window may have clipped a key detail, or the agent may be stuck choosing between equally plausible next steps. Even when nothing is “broken,” long-running reasoning can feel like a hang if there’s no visible progress marker. The first design decision is whether your system treats silence and repetition as acceptable, or as conditions that trigger a recovery path.
Is it stuck, or just thinking slowly?
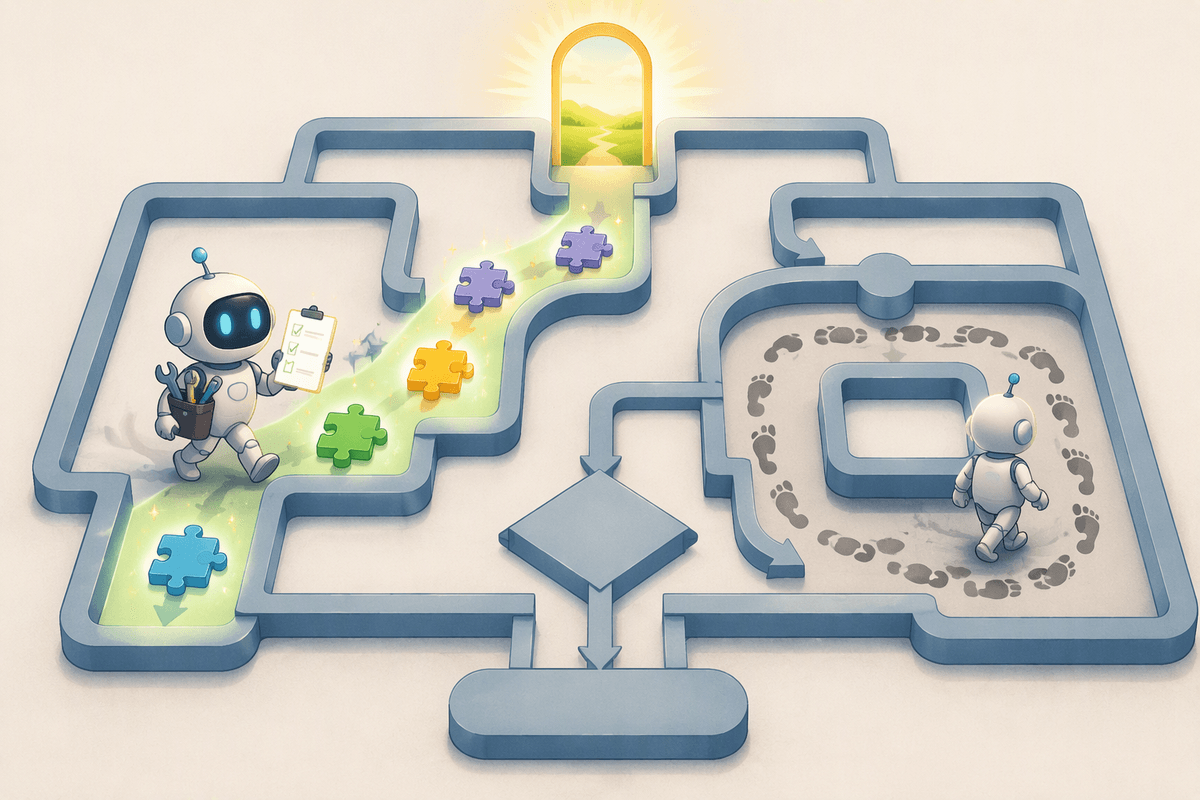
In a real workflow, “stuck” and “slow” can look the same: a spinner, a stream of status messages, or a chatty narrative that never lands. The difference is whether the agent is producing new, verifiable state. Slow thinking still changes something you can observe: it gathers a missing field, executes a tool call, reduces the open questions, or narrows a plan into a concrete next action. Stuck behavior repeats the same intent (“checking,” “searching,” “validating”) without any new artifact, decision, or external result.
Two checks usually separate them. First, is there forward motion in the tool layer (requests sent, responses received, files edited, tickets updated), or just re-justification in text? Second, is the agent converging, or widening the search space with every turn? Slow runs have a predictable cost curve; stuck runs inflate latency with no increased confidence. Without instrumentation, you’ll misclassify both, which is why timeouts need companion signals like step counts, tool error rates, and “last meaningful output” timestamps.
Common ways agents get stuck in practice
A familiar pattern is the “tool treadmill”: the agent keeps calling the same endpoint with slightly different parameters, or retries after a 400/401/429 without changing anything that would make success more likely. Sometimes the error is visible but unactionable (a generic “failed”); other times the tool succeeds but returns empty results, and the agent treats “no data” as “keep searching.” In coding flows, this shows up as reopening the same files, rerunning tests that already failed, or proposing the same patch with minor wording changes.
Another common stall is decision paralysis caused by underspecified goals or conflicting constraints. If “resolve the ticket” could mean refund, replacement, or explanation, the agent may loop through options without committing—especially when it lacks permission to choose. Context and access problems create quieter stalls: key details fall out of the context window, credentials expire mid-run, or a required system isn’t reachable from the agent’s network. These failures consume tokens and latency while producing outputs that look like progress but don’t reduce uncertainty.
What the system should do before users notice
Users have little patience for an AI agent that appears to be doing nothing, so a lack of visible progress needs to be treated as an operational problem rather than a minor interface issue. The system should monitor for signs of a stalled run, including repeated tool calls with unchanged inputs, rising error rates, no new outputs such as drafts or patches, and long periods without a meaningful state change. When these signals appear, it should stop the loop, save the current state, and try a limited alternative instead of continuing indefinitely.
Three safeguards help keep the workflow moving. First, set time and step limits for individual tools and the overall task so repeated retries cannot consume resources without making progress. Second, adapt to tool errors: refresh credentials or request authorization after a 401 response, slow down after a 429 response, and change the search strategy or escalate when repeated queries return nothing useful. Third, report progress through verifiable updates, such as “retrieved 12 tickets,” “created patch file,” or “waiting for CRM access.” These messages give users a concrete reason for the delay rather than leaving them to guess. Implementing this approach requires instrumentation, structured logs, and clear definitions of meaningful progress for each workflow, but those foundations make stalled runs easier to detect, recover, and explain.
Recovery playbook: retry, replan, ask, or hand off
When the tripwires fire, the first move is a bounded retry, but only if something materially changed: a transient network error, a rate limit, or a known flaky dependency. Retries should carry new information (fresh auth, backoff jitter, different pagination) and stop after a small budget. Otherwise you burn latency and tokens while teaching the agent that persistence is a strategy. A good rule is “retry on transport, not on semantics”: if the tool returned a valid response that says “no results,” looping won’t help.
If a retry won’t change the outcome, replan around the constraint. That can mean switching tools (search the data warehouse instead of the CRM), relaxing a nonessential requirement, or producing an intermediate artifact the user can act on (a draft reply, a diff, a shortlist of candidates). When the agent is blocked by missing intent, permissions, or data, it should ask a single, high-leverage question with options, not a vague “need more info.” If it still can’t proceed safely, hand off with a crisp packet: current hypothesis, what was tried, errors seen, and the minimal next action for a human.
Designing prompts and tools to reduce stalls
In many teams, the stall starts upstream in how the job is framed. Prompts that mix goals (“resolve the ticket”) with vague constraints (“be helpful”) invite the agent to keep narrating instead of committing. Better prompts force early commitments: define “done” as a concrete artifact, require a short plan with numbered steps, and mandate a “stop and ask” rule when a required field, permission, or tool result is missing. Adding a lightweight “progress contract” helps: after each step, the agent must either produce an artifact, record a decision, or cite a tool result—otherwise it must change strategy.
Tool design matters just as much. Tools should return structured, actionable errors (auth needed, rate-limited, invalid input, empty dataset) and include enough metadata for the agent to adapt (retry-after, paging cursors, partial results). Idempotent write operations, dry-run modes, and explicit permission checks reduce the fear-driven loop where the agent keeps “verifying” rather than acting. This requires extra engineering and product agreement on schemas, budgets, and what “meaningful output” looks like per workflow.
Measuring progress so you can improve it
You can’t improve stalls you can’t see, so treat “progress” as a measurable signal, not a vibe. Track time since last meaningful state change (tool result, file diff, ticket update), step counts, repeated-call fingerprints (same tool plus near-identical inputs), and the rate of “empty but valid” responses. Log why the agent stopped: timeout, step cap, tool error, missing permission, ambiguity question, or safe handoff. Then review runs by workflow, not averages—p95 latency hides loops.
Capturing artifacts, traces, and tool payloads can be expensive and sensitive. Keep lightweight counters by default, sample full traces, and redact aggressively. The payoff is clear knobs: tighten retries where error rates spike, improve prompts where ambiguity drives questions, and fix tools where “success with no data” correlates with churn.